My experiences and learnings on Technology, Leadership, Domains, Life and on various topics as a reference!
What you can expect here, it could be something on Java, J2EE, Databases, or altogether on a newer Programming language, Software Engineering Best Practices, Software Architecture, SOA, REST, Web Services, Micro Services, APIs, Technical Architecture, Design, Programming, Cloud, Application Security, Artificial Intelligence, Machine Learning, Big data and Analytics, Integrations, Middleware, Continuous Delivery, DevOps, Cyber Security, Application Security, QA/QE, Automations, Emerging Technologies, B2B, B2C, ERP, SCM, PLM, FinTech, IoT, RegTech or any other domain, Tips & Traps, News, Books, Life experiences, Notes, latest trends and many more...
Having clean software architecture and staying conform to pre-defined design principles from start of the project is one of the best ways to avoid possible technical debt in the future of that software system. Clean Software Design is a key point for an effective software product.
Let us have a look at some important principles, rules, guidelines that ensure a clean software design:
Principles:
Loose Coupling — if classes use each other, they are coupled together. The less classes are coupled, the easier is to change them.
High Cohesion — degree to which elements of a whole belong together. Components of the class should be highly cohesive.
Locality — Changes, maintenance, extensions are only local. This leads to no harming whole environment.
Removeable — Software Components should be easily removeable.
Small Components — software system should be only of small components ideally each doing only one task.
Class Design:
Single Responsibility Principle (SRP) — class should do only one task.
Open Closed Principle (OCP) — class should be extended not modified.
Liskov Substitution Principle (LSP) — child classes must be able to replace their super classes.
Dependency Inversion Principle (DIP) — dependeny is reversed: high level components are free of low-level components.
Interface Segregation Principle (ISP) — interfaces should be small: classes should not implement unnecessary methods.
Cohesion Principles:
Release Reuse Equivalency Principle (RREP) — only together releaseable components should be bundled together.
Common Closure Principle (CCP) — classes that change together should be bundled together.
Common Reuse Principle (CRP) — classes that are used together should be bundled together.
Coupling Principles:
Acyclic Dependencies Principle (ADP) — no dependency cycles.
Stable Dependencies Principle (SDP) — depend on direction of stability.
Stable Abstractions Principle (SAP) — the more abstract, the more stable.
High-Level Architecture:
Keep Configurable Data at High Levels — constants or config datas should be kept in high level.
Don’t Be Inconsistent— have a convention, principle, rule or guidelines and always follow them.
Prefer Polymorphism To If/Else or Switch/Case.
Separate Multi-Threading Code — isolate multi-thread from rest of the code.
Only one level of Abstraction per layer — stay conform to existing abstraction layers.
Fields Not Defining State — fields holding data that does not belong to the state of the instance but are to hold temporary data. Use local variables or extract to a class abstracting the performed action.
Micro Layers — avoid unnecessary design layers.
Singletons / Service Locator — Make use of dependency injection.
Base Classes Depending On Their Derivatives — Base classes should work with any derived class.
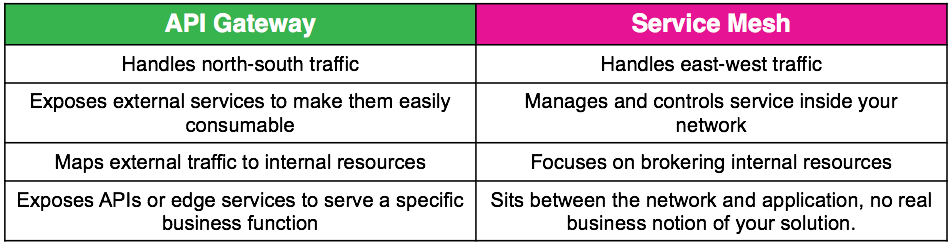
Service Mesh "How is it different from an API gateway?" It's a good question. The overlap between API gateway and service mesh patterns is significant. They can both handle service discovery, request routing, authentication, rate limiting, and monitoring, but there are differences in architectures and intentions. A service mesh's primary purpose is to manage internal service-to-service communication, while an API Gateway is primarily meant for external client-to-service communication.
Do You Need Both?
You may be wondering if you need both an API gateway and a service mesh. Today you probably do, but as service mesh evolves, we believe it will incorporate much of what you get from an API gateway today.
The main purpose of an API gateway is to accept traffic from outside your network and distribute it internally. The main purpose of a service mesh is to route and manage traffic within your network. A service mesh can work with an API gateway to efficiently accept external traffic then effectively route that traffic once it's in your network. The combination of these technologies can be a powerful way to ensure application uptime and resiliency while ensuring your applications are easily consumable.
In a deployment with an API gateway and a service mesh, incoming traffic from outside the cluster would first be routed through the API gateway, then into the mesh. The API gateway could handle authentication, edge routing and other edge functions, while the service mesh provides fine-grained observability of and control of your architecture.
The interesting thing to note is that service mesh technologies are quickly evolving and are starting to take on some of the functions of an API gateway. A great example is the introduction of the Istio v1alpha3 routing API which is available in Aspen Mesh 1.0. Prior to this, Istio had used Kubernetes ingress control which is pretty basic so it made sense to use an API gateway for better functionality. But, the increased functionality introduced by the v1alpha3 API has made it easier to manage large applications and to work with protocols other than HTTP, which was previously something an API gateway was needed to do effectively.
What The Future Holds
The v1alpha3 API provides a good example of how a service mesh is reducing the need for API gateway capabilities. As the cloud-native space evolves and more organizations move to using Docker and Kubernetes to manage their microservice architectures, it seems highly likely that service mesh and API gateway functionality will merge. In the next few years, we believe that standalone API gateways will be used less and less as much of their functionality will be absorbed by service mesh.
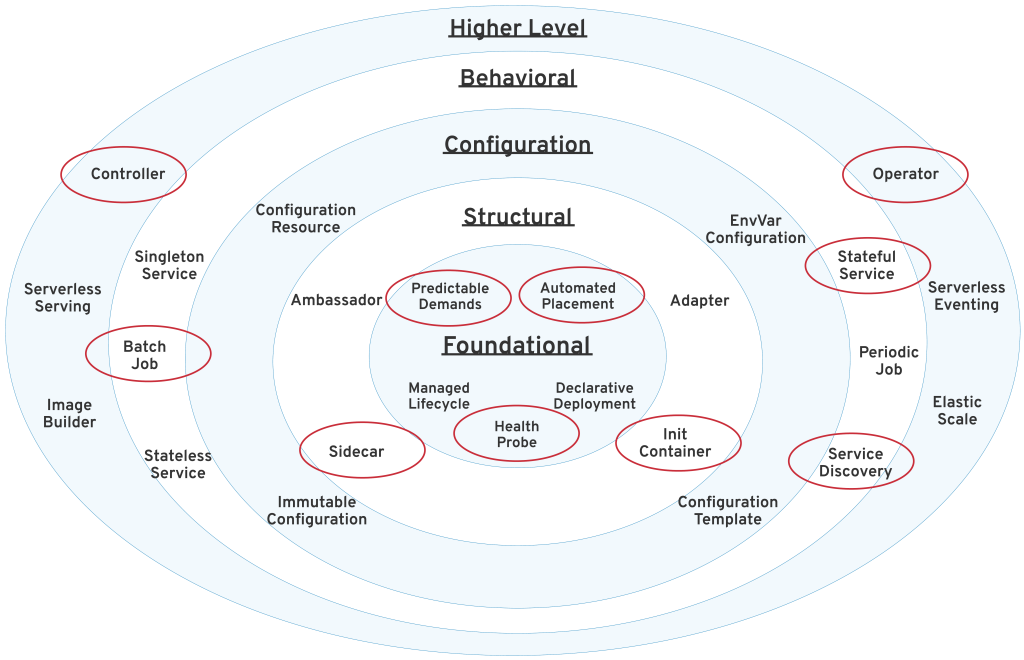
Here are the must-know top 10 design patterns for beginners synthesized from the Kubernetes Patterns book. Getting familiar with these patterns will help you understand foundational Kubernetes concepts, which in turn will help you in discussions and when designing Kubernetes-based applications.
There are many important concepts in Kubernetes, but these are the most important ones to start with:
Source: Kubernetes Patterns
To help you understand, the patterns are organized into a few categories below, inspired by the Gang of Four’s design patterns.
Foundational patterns
These patterns represent the principles and best practices that containerized applications must comply with in order to become good cloud-native citizens. Regardless of the application’s nature, you should aim to follow these guidelines. Adhering to these principles will help ensure that your applications are suitable for automation on Kubernetes.
Health Probe pattern
Health Probe dictates that every container should implement specific APIs to help the platform observe and manage the application in the healthiest way possible. To be fully automatable, a cloud-native application must be highly observable by allowing its state to be inferred so that Kubernetes can detect whether the application is up and ready to serve requests. These observations influence the life-cycle management of Pods and the way traffic is routed to the application.
Predictable Demands pattern
Predictable Demands explains why every container should declare its resource profile and stay confined to the indicated resource requirements. The foundation of successful application deployment, management, and coexistence on a shared cloud environment is dependent on identifying and declaring the application’s resource requirements and runtime dependencies. This pattern describes how you should declare application requirements, whether they are hard runtime dependencies or resource requirements. Declaring your requirements is essential for Kubernetes to find the right place for your application within the cluster.
Automated Placement patterns
Automated Placement explains how to influence workload distribution in a multi-node cluster. Placement is the core function of the Kubernetes scheduler for assigning new Pods to nodes satisfying container resource requests and honoring scheduling policies. This pattern describes the principles of Kubernetes’ scheduling algorithm and the way to influence the placement decisions from the outside.
Structural patterns
Having good cloud-native containers is the first step, but not enough. Reusing containers and combining them into Pods to achieve the desired outcome is the next step. The patterns in this category are focused on structuring and organizing containers in a Pod to satisfy different use cases. The forces that affect containers in Pods result in these patterns.
Init Container pattern
Init Container introduces a separate life cycle for initialization-related tasks and the main application containers. Init Containers enable separation of concerns by providing a separate life cycle for initialization-related tasks distinct from the main application containers. This pattern introduces a fundamental Kubernetes concept that is used in many other patterns when initialization logic is required.
Sidecar patterns
Sidecar describes how to extend and enhance the functionality of a pre-existing container without changing it. This pattern is one of the fundamental container patterns that allows single-purpose containers to cooperate closely together.
Behavioral patterns
These patterns describe the life-cycle guarantees of the Pods ensured by the managing platform. Depending on the type of workload, a Pod might run until completion as a batch job or be scheduled to run periodically. It might run as a daemon service or singleton. Picking the right life-cycle management primitive will help you run a Pod with the desired guarantees.
Batch Job patterns
Batch Job describes how to run an isolated, atomic unit of work until completion. This pattern is suited for managing isolated atomic units of work in a distributed environment.
Stateful Service patterns
Stateful Service describes how to create and manage distributed stateful applications with Kubernetes. Such applications require features such as persistent identity, networking, storage, and ordinality. The StatefulSet primitive provides these building blocks with strong guarantees ideal for the management of stateful applications.
Service Discovery pattern
Service Discovery explains how clients can access and discover the instances that are providing application services. For this purpose, Kubernetes provides multiple mechanisms, depending on whether the service consumers and producers are located on or off the cluster.
Higher-level patterns
The patterns in this category are more complex and represent higher-level application management patterns. Some of the patterns here (such as Controller) are timeless, and Kubernetes itself is built on top of them.
Controller pattern
Controller is a pattern that actively monitors and maintains a set of Kubernetes resources in a desired state. The heart of Kubernetes itself consists of a fleet of controllers that regularly watch and reconcile the current state of applications with the declared target state. This pattern describes how to leverage this core concept for extending the platform for our own applications.
Operator pattern
An Operator is a Controller that uses a CustomResourceDefinitions to encapsulate operational knowledge for a specific application in an algorithmic and automated form. The Operator pattern allows us to extend the Controller pattern for more flexibility and greater expressiveness. There are an increasing number of Operators for Kubernetes, and this pattern is turning into the major form of operating complex distributed systems.
Summary
Today, Kubernetes is the most popular container orchestration platform. It is jointly developed and supported by all major software companies and offered as a service by all of the major cloud providers. Kubernetes supports both Linux and Windows systems, plus all major programming languages. This platform can also orchestrate and automate stateless and stateful applications, batch jobs, periodic tasks, and serverless workloads. The patterns described here are the most commonly used ones from a broader set of patterns that come with Kubernetes as shown below.
Kubernetes Patters organized in different categories
Kubernetes is the new application portability layer and the common denominator among everybody on the cloud. If you are a software developer or architect, the odds are that Kubernetes will become part of your life in one form or another. Learning about the Kubernetes patterns described here will change the way you think about this platform. I believe that Kubernetes and the concepts originating from it will become as fundamental as object-oriented programming concepts.
The patterns here are an attempt to create the Gang of Four design patterns, but for container orchestration. Reading this article must not be the end, but the beginning of your Kubernetes journey. Happy kubectl-ing!
A firm introduction on the blockchain can be found from here at https://blockgeeks.com/guides/what-is-blockchain-technology/ or https://en.wikipedia.org/wiki/Blockchain as a refresher... Now, quickly let me jump onto how these blocks data are getting verified with the right synchronization across all the nodes or blocks? How can we check the consistency, data verification, and data synchronization, etc?
The data structure behind it can be Merkle trees, Merkle tree also known as a hash tree is a data structure used for data verification and synchronization. It is a tree data structure where each non-leaf node is a hash of its child nodes. All the leaf nodes are at the same depth and are as far left as possible. It maintains data integrity and uses hash functions for this purpose.
The more uses of these Merke trees are below:
If you wanted to do data verifications across your distributed systems
DLTs (Distributed Ledger Technologies) such as Bitcon, Ethereum
Well known distributed databases like Apache Cassandra
The C4 model for visualizing software architecture
What is C4?
Context, Containers, Components, and Code
What tools can I use? How to create?
There are many tools available and can be used, and my favorite is http://draw.io/
Why one should use it?
Usually, there are many ways one can visualize the software architecture diagrams including UML, and yet, if you are going in a faster and agile of handling software architecture and wanted to visualize easily, then you can go for the C4 model
Where it is widely used?
To communicate your software architecture diagrams effectively in fast-paced environments
The more highly available system means that the less downtime you have to deal with...
Imagine,
The five nines, 99.999 availability means ~5 mins of downtime a year
The four nines, 99.99 availability means ~ 50 mins of downtime a year
The three nines, 99.9 availability means ~9 hours of downtime a year
The two nines, 99 availability means roughly 3 and half days of downtime a year
So, why are we concerned about the downtime? the more downtime you have means the less you attract your customers as I presume most of the systems or applications are accessible 24/7 and it means that round the clock!
We might be thinking that - oh, yeah - we have good ample of downtime in our hands to deal with it, but believe me, if you don't design the system very well with right practices and processes in place then it would be very hard to even achieving the two nines availability too, so, you have to really work very hard and smart to deal with it in an effective manner.
Some tips to utilize the downtime effectively for your systems or platforms are:
Make sure to eliminate any single point of failures; Especially handing with the third party API endpoints or dependent systems those are not in your control by having right retry frameworks and circuit breaker patterns
Observability and Monitoring with clear alerts and notifications in place
Have an efficient CI/CD pipelines with right checks on various stages of your configured environment to stop promoting the bad code (faulty code which has issues, and it can be performance issues as well)
Have well-defined deployments and the changed code propagation with
Blue-green deployments (having two identical production environments, one is blue and other one is green)
Canary deployments (by routing smaller traffic to the new changes and slowly increase the traffic)
Encourage A/B testing within your product features release where you are not sure on some of the features; also, promote canary releases too
Lastly, try to have a very diligent process by imagining all dimensions how your system can fail with scenarios(and that has come from your proactive resiliency testing activities) so that you have right tools to troubleshoot, tune and respond for any unknown hardware or network failures
We all know SOA(that is Service Oriented Architecture), but what is ROA?
ROA stands for Resource-Oriented Architecture, and what are the Resources here? The resources are nothing but your RESTful services or interfaces. This would become a paradigm shift in the overall web services world very soon and every company would adapt to the ROA instead of SOA to gain more traction in their way of doing businesses and services.
Basics of RESTful services or interfaces:
REST is an architecture style for designing networked applications. It stands for REpresentational State Transfer.
What is not REST?
A language
A framework
A brand
Software that you can download and make it run.
A standard (W3C hasn't accepted, so it continues as open style)
REST constraints
As REST creator, Roy Fielding describes in his doctoral dissertation, it was conceived as a whole sets of needs, shaped by the constraints of the environment in which this system was going to be implemented. Such constraints are:
Client-Server
Uniform Interface
Stateless
Cacheable
Layered System
Code on demand (optional)
Some definitions before
State
A state is that which the server application cares about to fulfill the request. This is the chunk of information that is sent by the server in every response.
Resource
A resource is data that defines a model representation. This might be the stored data in the database.
Note, that, a state is a piece of information that depends on the request and the client that is asking for; while the resource is information that is constant through all clients (of course until it needs to be updated).
Idempotence
In terms of computer science, this term has a different meaning. It describes an operation that will produce the same result whether it is being called once or many times. In other words, making multiple identical requests has the same effect as making a single one. Imagine a client asking a server to update the resource, setting its property to the value of 20. No matter how many times you ask this. You'll have the same effect on the database.
Safety
Speaking of RESTful approach, safety means the ability of a method to not change the state of a resource in the server. This means, all methods that are safety doesn't alter the information (database). Consequently, clients can make safe requests repeatedly without worry of side effects on the server.
Client-Server
The web operates in this way: where there is a web server delivering content, that is being interpreted by a browser or a mobile app. In this case, the server is usually the web application, and the client is the browser, or mobile app. In this scenario, the information flow happens in one way: The client does a request to the server, which after processing such request, delivers a response.
Uniform Interface
This constraint defines that the interface between any server, and all possibilities of clients, should be the same. This decouples the architecture between client and server, giving the ability to both to evolve separately.
Stateless
Here it comes what REST means. Representational State Transfer means that each request has to carry with the necessary state to handle the transaction. This releases the server from keeping a state of information between multiple requests. Are you familiar with the concept of SESSION in web development ? REST avoids the existence of it. And because of this, the server gets the ability to scale better.
Cacheable
This constraint says that each response must define implicitly or explicitly, whether it is a cacheable resource, or not. By telling a client that such content is cacheable, it optimizes the performance of communication, since the client will avoid unnecessary requests for static data.
Layered System
This says that from the server-side, scalability may be improved in such way that the client won't notice whether it is dealing in one server or an intermediary app. That let the server side infrastructure to escalate through load balancing, shared caches, and security middlewares.
Code on demand (optional)
This means that the server might also delivers logic to the client, such as javascript content that might be interpreted by the client. This is optional, and I think is nowadays not used, since the appearance of Single Page Apps.
2. REST How-to
Principles
Know the best RESTful practices from the community.
1. Use meaningful HTTP verbs.
You know them: GET, POST, PUT, DELETE. Such verbs already mean an intention, and the purpose of REST principles is to use this as an advantage to set clarity for t he API.
2. Sensible resource names.
In the old times of web development, a resource used to accept parameters from long query strings, such as /api?model=user&id=123. By following this principle, the URI (also called resource name) shoud be as well meaninful as the HTTP verb. So rewriting the previous URI to a meaningful one, would be /user/123.
3. XML and JSON
That's up to the necessities of the client. If you're going to provide a public API, having both is a good idea, since you have a broad scope of clients that can interact with your app. But we suggest to favor JSON over XML. This is because the simplicity of its nature as a data container. Also, since most of the clients are browsers, JSON is javascript syntax, which makes perfect to be parsed by the client side. If you're going to render XML, avoid namespaces, and think of XML as a data container, which is the purpose of the API.
4. Create Fine-Grained Resources
Instead of starting with complex services, focus on basic, simple resources, and provide CRUD operations on them. Additionally you will add complex services over that system.
5. Idempotence for PUT and DELETE
This means that by sending a request with the same state (data) to the server, you'll have the same effect on the domain/database.
6. Safety for HEAD, GET, OPTIONS and TRACE
These methods are defined to be safe, this means, to not alter the state in the server.
HTTP Verbs
Technically, there are 8 HTTP Methods. The most used in RESTful APIs are only 4 (GET, POST, PUT and DELETE). They cover CRUD operations on a resource.
GET
POST
PUT
DELETE
OPTIONS
HEAD
TRANCE
CONNECT
1. GET
GET is used to retrieve information from the server, specifically information of a resource. If the request goes well, it returns a 200 code. Otherwise, it might return an error code, like 404 or 400
Examples:
# Gets a list of all users
GET /api/users
# Gets details for user with id = 23
GET /api/users/23
# Gets a list of all orders belonging to user with id = 23
GET /api/users/23/orders
2. POST
POST is used for creating a resource. It accepts usually a JSON body in the request. This data is the state for the resource that is going to be created. If the execution goes well, it returns a status code 201, with a location header with the link to the newly created resource. The POST operation is not safe, since it affects the state of information. It is also not an idempotent operation, since every time a resource creation is requested, the id attribute will be auto-incremented, making the effect of this operation, unique every time.
Examples:
# Inserts a user
POST /api/users
# body
{
  name: "User"
}
3. PUT
PUT is used for updating a resource. It accepts usually a JSON body which contains the data of the resource that will be updated. On succesful execution, it returns a status code 200. PUT is not a safe operation, since it affects the state of the resource in the server information. However, PUT is encouraged to be an idempotent operation. This is, by knowing the id of the resource that will be updated, and having certain values that will be written, every operation will cause the same effect on the resource status in the server.
Examples:
# Updates a user
PUT /api/users/23
# body
{
  name: "User number 23"
}
4. DELETE
DELETE operation is used for deleting a resource identified by a URI. This is not a safe operation, since it affects the state of the resource in the server. If the operation goes well, it responds with a satus code of 200. DELETE operation is idempotent. This is, by calling this operation the first time, the resource will be deleted from the server information storage (database), and by calling the next times, the response should be the same: the resource is gone.
Examples:
# Deleting a user
DELETE /api/users/delete/23
Methods Cheatsheet
HTTP Method
Resource Operation
Example URI
Response code
Location Header
Safe
Idempotent
GET
Fetch
/api/users, /api/users/{id}
200
No
Yes
No
POST
Create
/api/users
201
Yes
No
No
PUT
Update
/api/users/{id}
200
No
No
Yes
DELETE
Delete
/api/users/{id}
200
No
No
Yes
Response Status Codes
We will cover the most common codes here. If you want to check the full list, you can go to MDN page.
2xx Success
3xx Redirect
4xx User error
5xx Server error
2xx Success codes
200 OK (default code)
201 Created (Response for POST requests)
202 Accepted (Response for DELETE requests)
4xxx Error codes
400 Bad request (generic)
401 Unauthorized
404 Not found (Bad URL, resource not found)
405 Method not allowed (wrong HTTP method)
409 Conflict
3. Examples
When you have your api in the same domain that your web app
// prefix of /api to encapsulate API into one set of controller/routes
GET /api/users
GET /api/users/{id}

//another controllers in the webapp, traditional HTML response
GET /users
GET /users/{id}
When you have a specific domain for API, but different versions ov if
// API v1
GET /v1/users
GET /v1/users/{id}

// API v2.3
GET /v2.3/users
GET /v2.3/users/{id}
One domain, simple URI
GET /users
GET /users/{id}
Nested resources
//users is the main resource
GET /users
GET /users/{id}

//contracts is a sub resource of users
GET /users/{id}/contracts
GET /users/{id}/contracts/{contract_id}
Valid Methods for URIs
GET /users
GET /users/{id}
POST /users
PUT /users/{id}
DELETE /users/{id}
Invalid Methods for URIs
// you cannot create by specifying a specific resource
POST /users/{id}

// You cannot update state for a URI that doesn't represent a specific resource
PUT /users

// You cannot delete a resource if you no provide its specific URI
DELETE /users